Qwen3.8-27B on RTX 5090 (32GB) + AMD Ryzen 7 9850X3D 8-Core Processor (8c) + 30GB
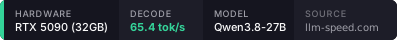
MeasuredOn 2026-09-05, Qwen3.8-27B Q4_K_M ran at 65.4 tok/s (chat-short) on an RTX 5090 (32GB) with llama.cpp. Run r_7mod38qsldj.
One of three repeat runs (measured 65.43 tok/s chat-short, 132 ms TTFT; 65.10 tok/s chat-long; llama.cpp 9725a31). For the median of all three repeats, memory use and fit, see Qwen3.8-27B on RTX 5090.
Workload results
| Workload | Backend | Model | decode tok/s | prefill tok/s | TTFT | p50 | p95 |
|---|---|---|---|---|---|---|---|
| chat-short | llama.cpp@1 (9725a31) | Qwen3.8-27BQ4_K_M | 65.43tok/s | 865.3tok/s | 132ms | 15.1ms | 15.2ms |
| chat-long | llama.cpp@1 (9725a31) | Qwen3.8-27BQ4_K_M | 65.10tok/s | 3,501.1tok/s | 909ms | 15.3ms | 15.4ms |
Reproduce on your machine
Start with this model and workload selection. This command does not capture the original artifact, backend version or server settings:
Match quantization, context capacity, caching and runtime settings for a useful comparison. Duration varies by workload and hardware; the published client may differ from this run's version. How it's measured.
Share this run
Copy the short link, a Reddit-ready summary, or a README badge. Every number is the measured result on this page, and each badge links back to it.
https://llm-speed.com/r/r_7mod38qsldjRelated benchmarks
- More Qwen3.8-27B benchmarks — every backend and rig that has run this model.
- More RTX 5090 (32GB) LLM benchmarks — every model measured on this hardware.
Provenance
- Run ID
- r_7mod38qsldj
- Fingerprint hash
- 013ca61a09d17996
- Public key
- 0tv44ISLy10gz6Oc6FJig3eWJVLwso9oKemSM4nicKM=
- Received
- 2026-09-05 20:41:27