gemma3 on RTX 4090 (24GB) + AMD EPYC 7443 24-Core Processor (24c) + 252GB
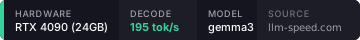
MeasuredOn 2026-07-02, gemma3 Q4_K_M ran at 195.0 tok/s (chat-short) on an RTX 4090 (24GB) with ollama. Run r_dlanfbgym0h.
RTX 4090 (24GB) + AMD EPYC 7443 24-Core Processor (24c) + 252GB
suite suite-v1
cli 0.0.3
signedE+zg15JJFh…
Embed badgesubmitted Jul 02, 2026Workload results
| Workload | Backend | Model | decode tok/s | prefill tok/s | TTFT | p50 | p95 |
|---|---|---|---|---|---|---|---|
| chat-short | ollama@0.31.1 | gemma3Q4_K_M | 195.0tok/s | 167.2tok/s | 706ms | 5.1ms | 5.4ms |
| chat-long | ollama@0.31.1 | gemma3Q4_K_M | 187.6tok/s | 3,254.1tok/s | 979ms | 5.3ms | 5.4ms |
| concurrent-decode | ollama@0.31.1 | gemma3Q4_K_M | 193.1tok/s | — | — | 5.1ms | 5.3ms |
| agent-trace | ollama@0.31.1 | gemma3Q4_K_M | 190.0tok/s | 3,543.4tok/s | 715ms | 5.2ms | 5.5ms |
Reproduce on your machine
Start with this model and workload selection. This command does not capture the original artifact, backend version or server settings:
Match quantization, context capacity, caching and runtime settings for a useful comparison. Duration varies by workload and hardware; the published client may differ from this run's version. How it's measured.
Share this run
Copy the short link, a Reddit-ready summary, or a README badge. Every number is the measured result on this page, and each badge links back to it.
https://llm-speed.com/r/r_dlanfbgym0hRelated benchmarks
- More gemma3 benchmarks — every backend and rig that has run this model.
- More RTX 4090 (24GB) LLM benchmarks — every model measured on this hardware.
Provenance
- Run ID
- r_dlanfbgym0h
- Fingerprint hash
- Public key
- E+zg15JJFhXi/5idiflZ8wsx7P2xrouvCpxt67yVxfE=
- Received
- 2026-07-02 16:53:44